Abstract
Scalable audio generation systems typically cascade a pretrained variational autoencoder (VAE) for audio compression and a latent diffusion model for distribution modeling. However, existing VAEs prioritize reconstruction fidelity without explicitly considering how readily the resulting latent distribution can be modeled by diffusion, potentially limiting generation quality. Recent work highlights the importance of aligning latent representations with the structure of the underlying data for diffusion modeling.
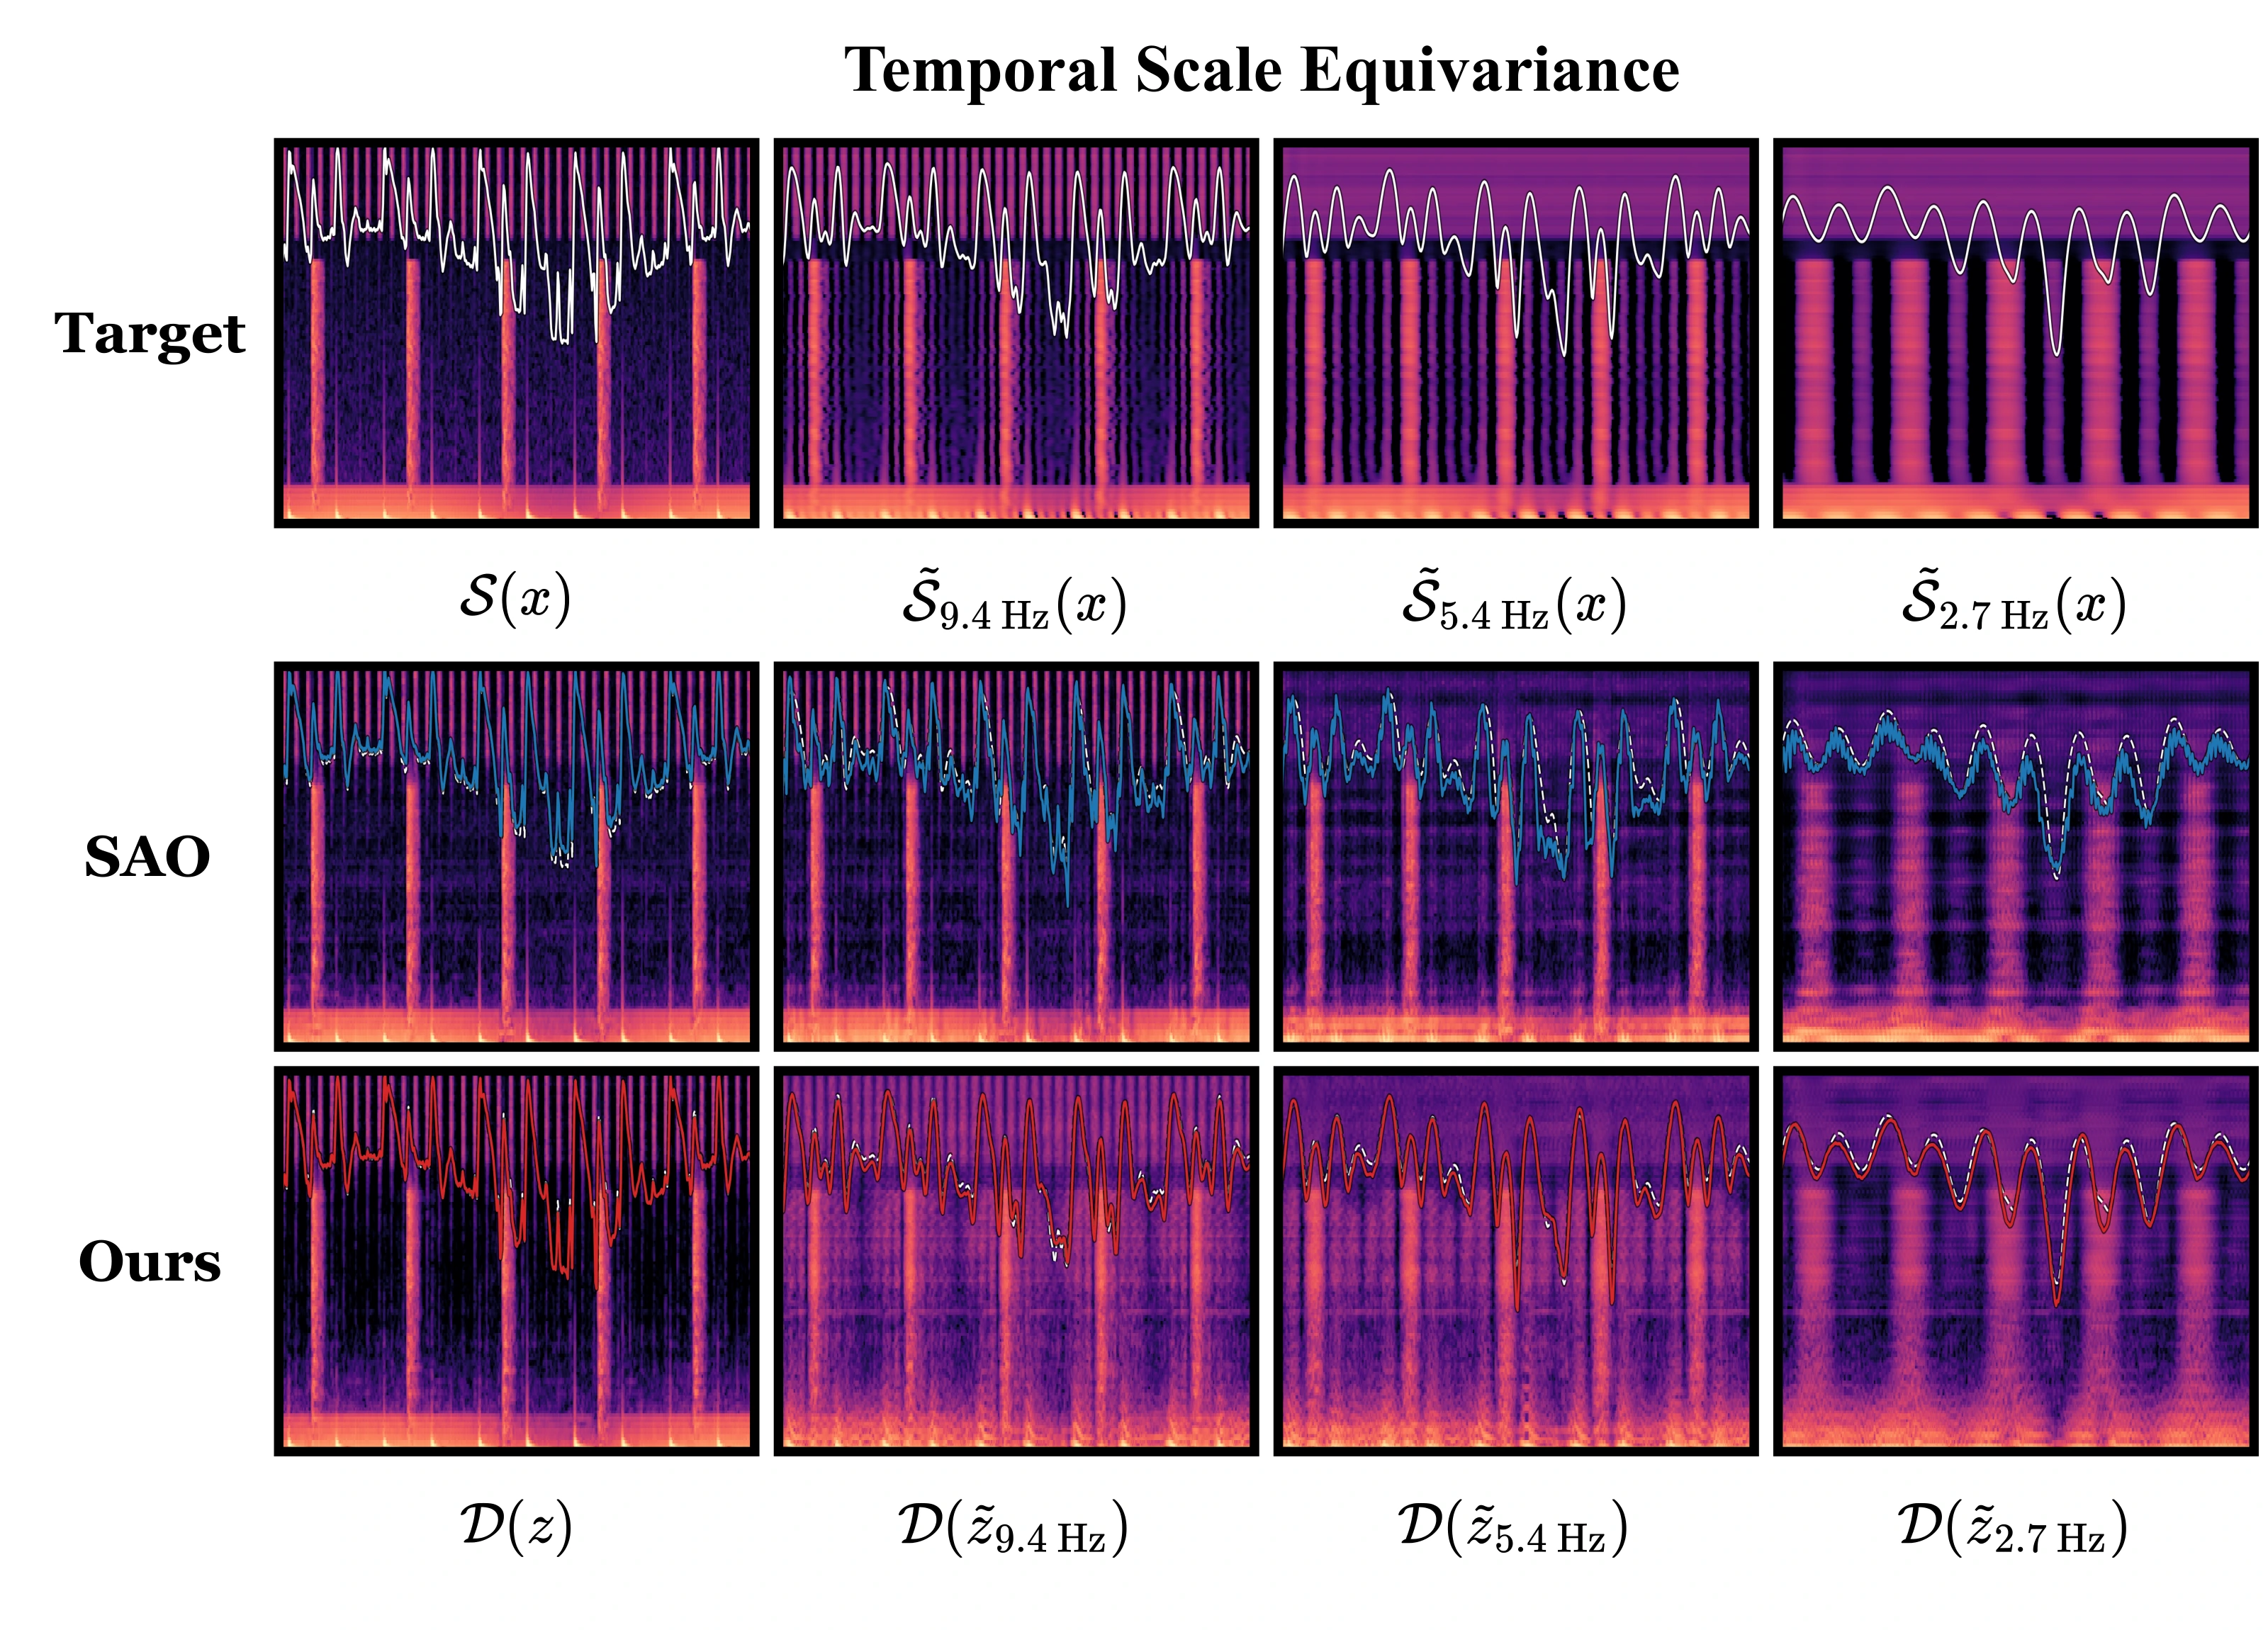
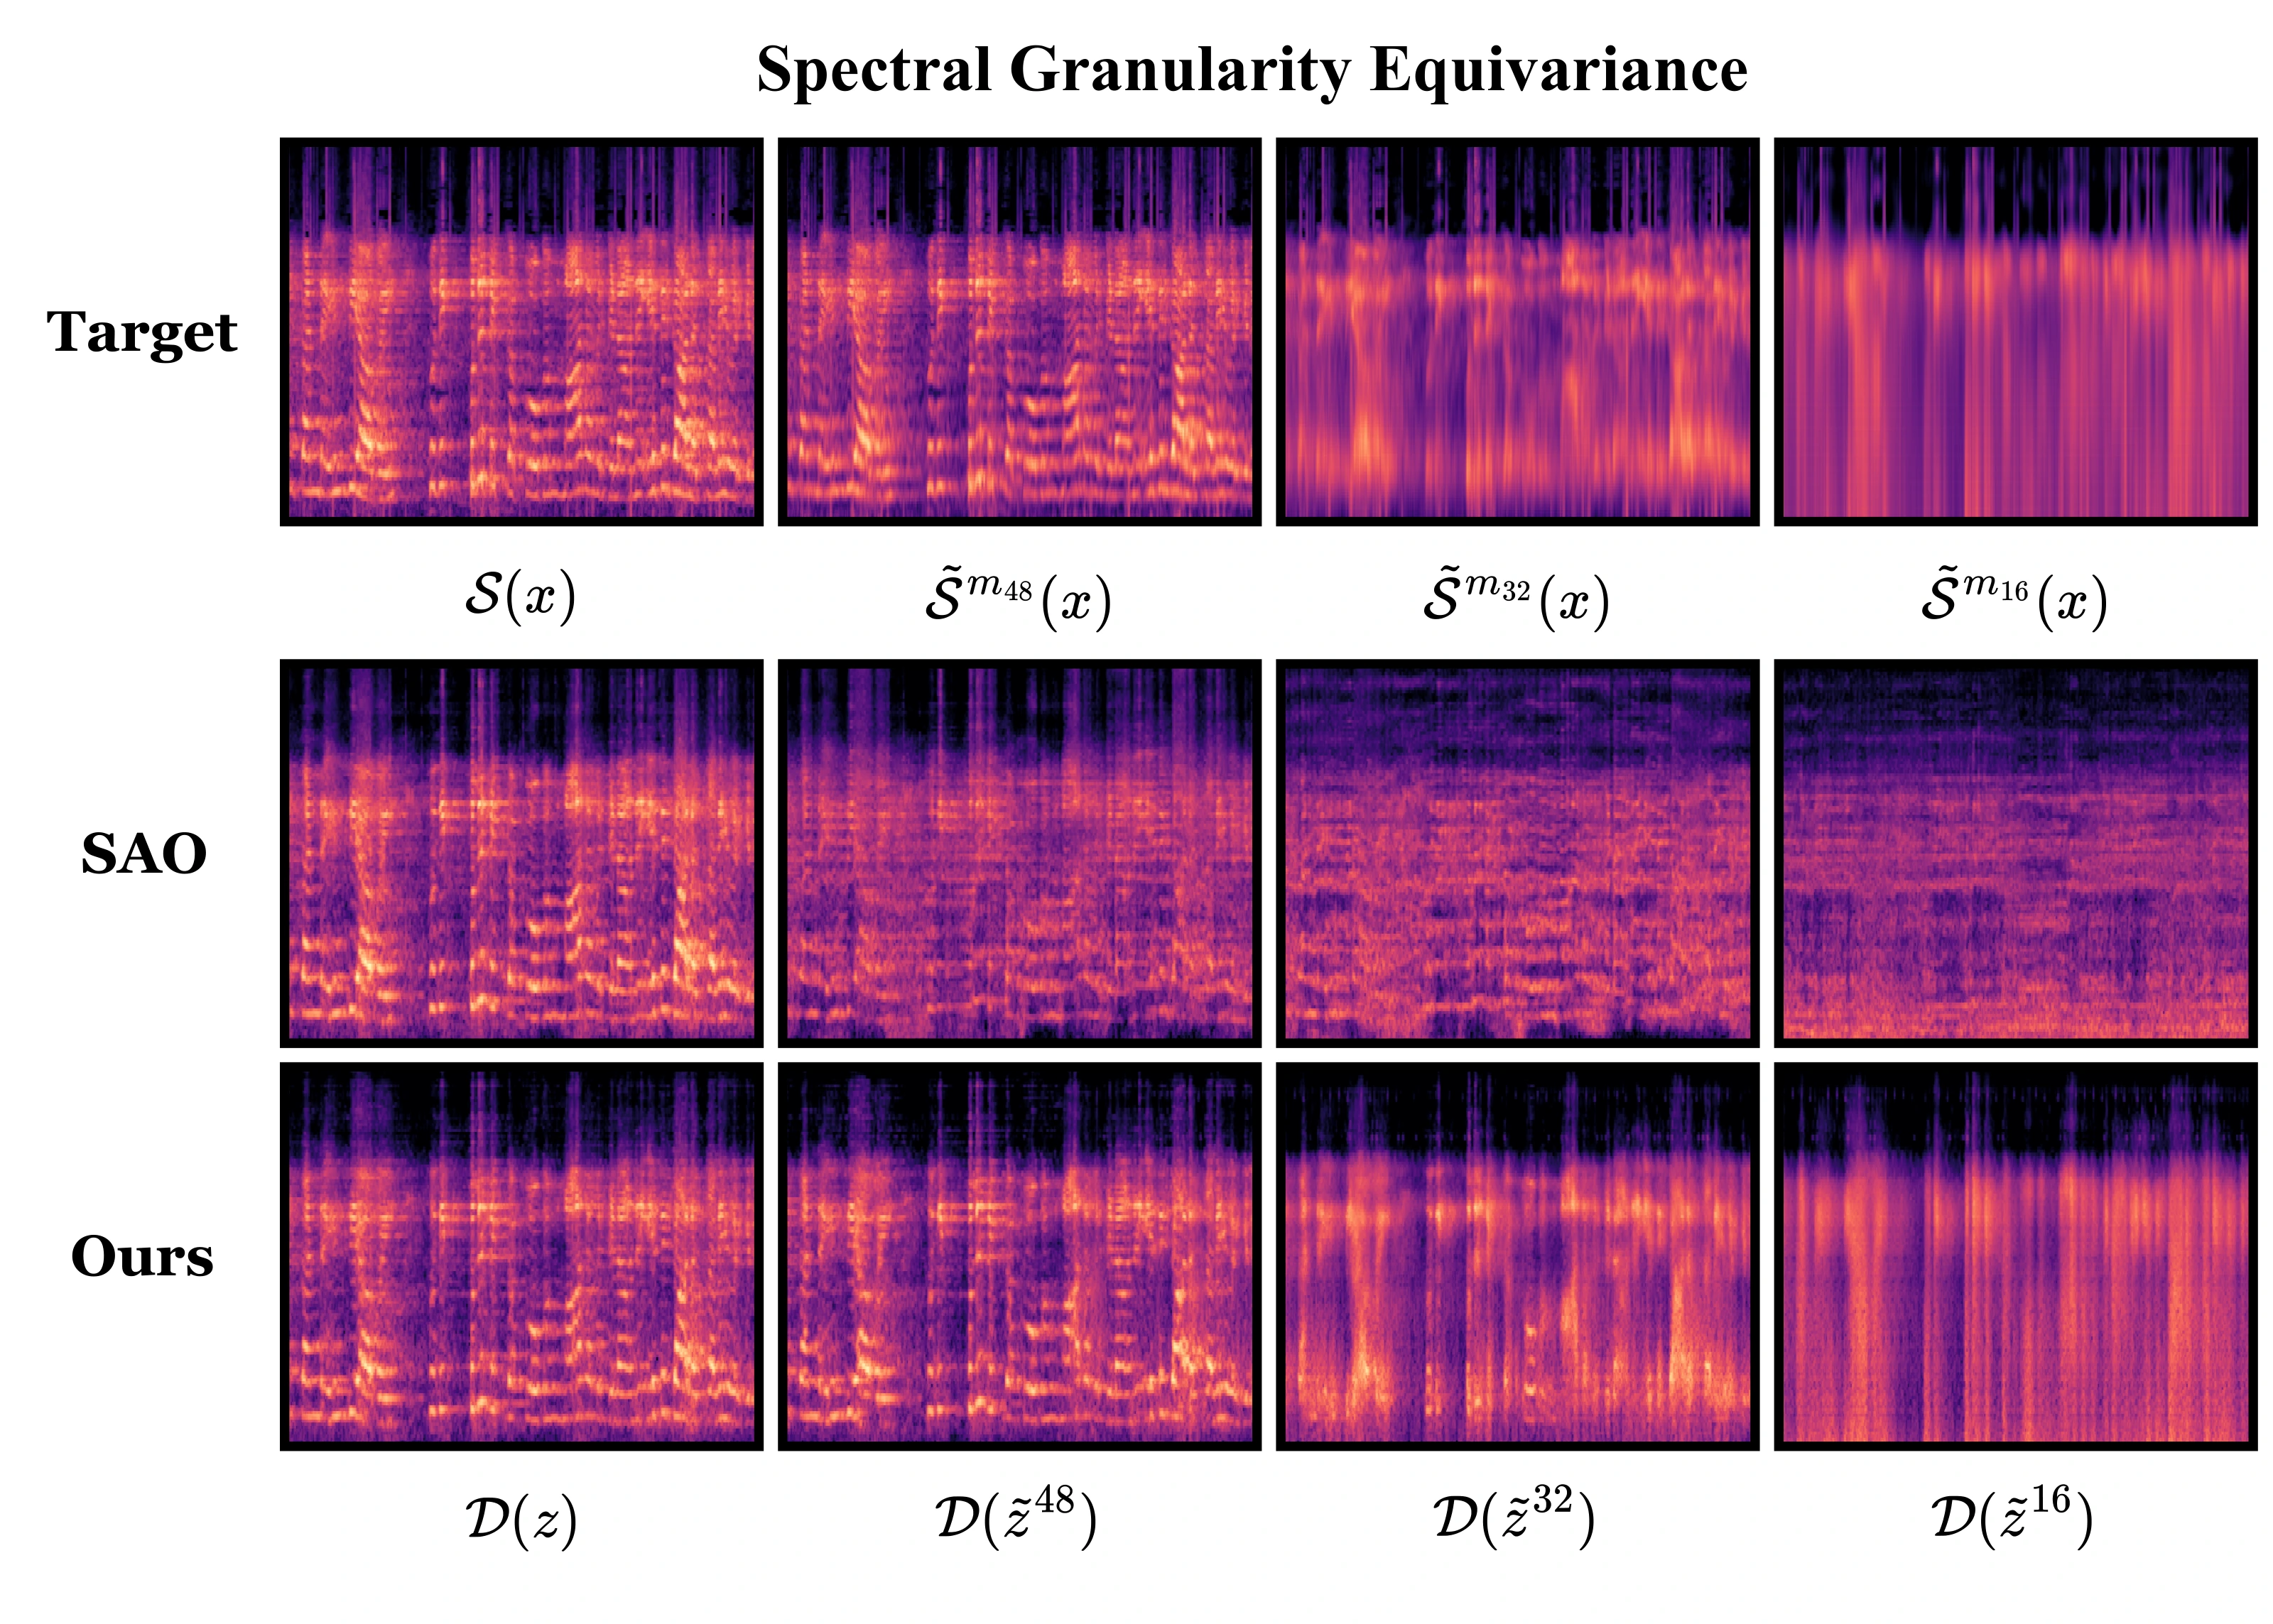
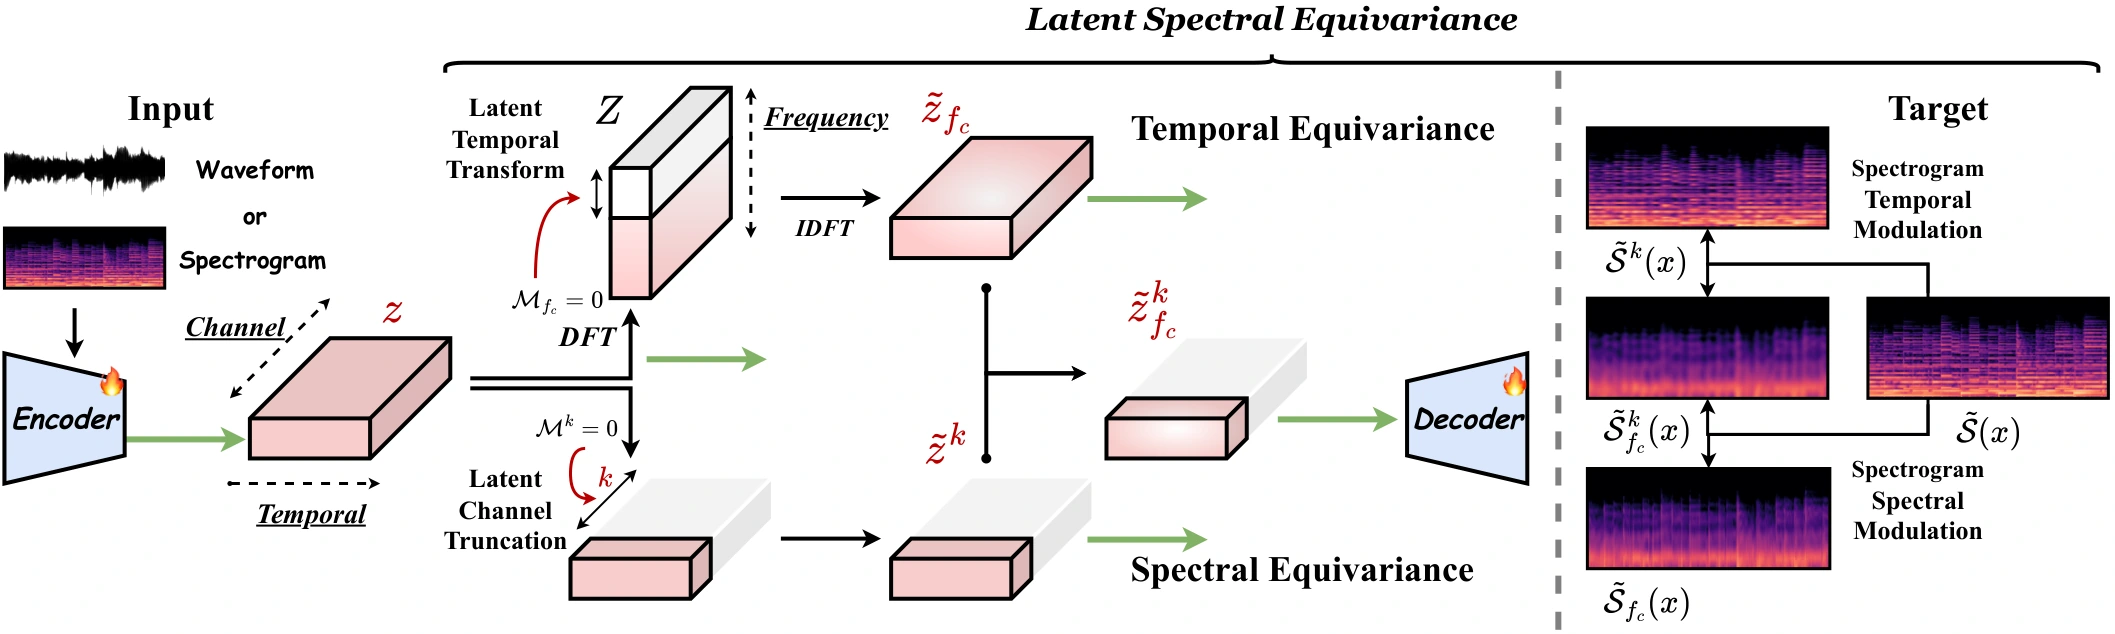
Building on this direction, we introduce Latent Spectral Equivariance (LatentEQ), a framework that introduces equivariance into audio VAE optimization by pairing latent transformations with corresponding spectrogram transformations. Specifically, temporal scale equivariance applies matched low-pass filtering along time, aligning slowly varying latent components with slowly varying acoustic structure. Spectral granularity equivariance pairs latent channel prefixes with frequency-smoothed spectrograms, organizing channels to progressively capture spectral envelopes and fine harmonic detail.
We instantiate LatentEQ on the VAEs of two well-known audio generation systems, Stable Audio Open and MMAudio, through fine-tuning without changing their architecture or adding loss terms. Comprehensive results demonstrate improved generation quality across waveform- and spectrogram-based VAEs and both text-to-audio and video-to-audio tasks, highlighting LatentEQ as an effective principle for learning structured audio latents.
Key Contributions
-
Temporal Scale
EquivariancePairs temporal low-pass filtering of the latent with the same coarsening of the target spectrogram, connecting slow latent variation to slowly varying acoustic structure.
-
Spectral Granularity
EquivariancePairs a prefix of latent channels with spectral smoothing of the target, so leading channels capture broad spectral envelopes and later channels progressively add fine detail.
-
One Principle Across
Audio Generation SystemsFine-tunes waveform and spectrogram VAEs without changing their architecture or adding loss terms. The frozen VAE then provides structured latents for standard diffusion training.
Text-to-Audio
AudioCaps
01.
Water trickles as birds chirp then drums begin to play
| Ground Truth | AudioLDM | Tango | MMAudio | LatentEQ (Spectrogram) | TangoFlux | AudioX | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel |  |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
02.
A quick repeat of applause followed by continued applause
| Ground Truth | AudioLDM | Tango | MMAudio | LatentEQ (Spectrogram) | TangoFlux | AudioX | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel |  |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
03.
A train horn blows as a train approaches with warning bells ringing
| Ground Truth | AudioLDM | Tango | MMAudio | LatentEQ (Spectrogram) | TangoFlux | AudioX | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel |  |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
04.
An infant and woman laughing as water splashes and birds chirp in the background
| Ground Truth | AudioLDM | Tango | MMAudio | LatentEQ (Spectrogram) | TangoFlux | AudioX | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel |  |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
05.
Tires squealing followed by an engine revving
| Ground Truth | AudioLDM | Tango | MMAudio | LatentEQ (Spectrogram) | TangoFlux | AudioX | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel |  |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
06.
Multiple basketballs bouncing on a hard surface and shoes squeaking as a man shouts in the distance
| Ground Truth | AudioLDM | Tango | MMAudio | LatentEQ (Spectrogram) | TangoFlux | AudioX | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel |  |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
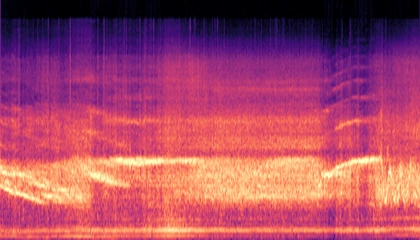
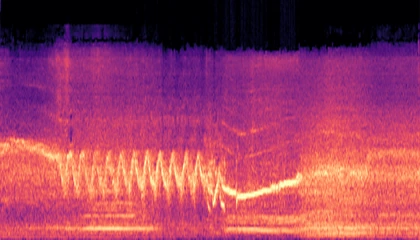
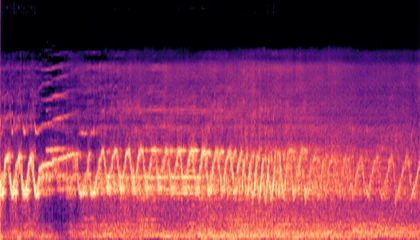
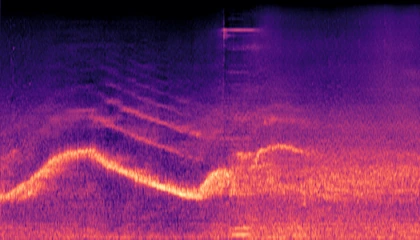
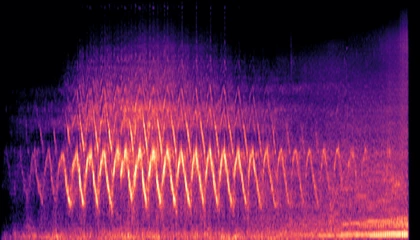
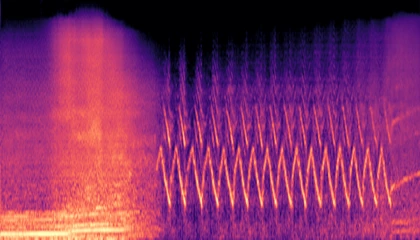
07.
Sirens ring and a vehicle speeds closer
| Ground Truth | AudioLDM | Tango | MMAudio | LatentEQ (Spectrogram) | TangoFlux | AudioX | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel |  |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
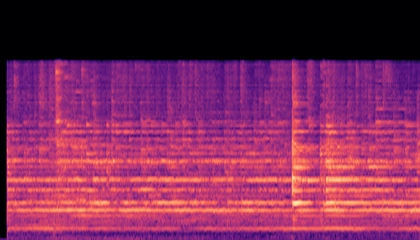
08.
Bells chime and ring
| Ground Truth | AudioLDM | Tango | MMAudio | LatentEQ (Spectrogram) | TangoFlux | AudioX | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel | 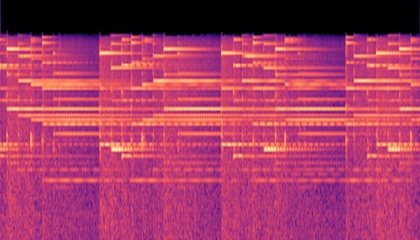 |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
Video-to-Audio
VGGSound
01.
| Ground Truth | V-AURA | Frieren | AudioX | MMAudio | LatentEQ (Spectrogram) | |
|---|---|---|---|---|---|---|
| Mel |  |  |  |  |  |  |
| Video |
02.
| Ground Truth | V-AURA | Frieren | AudioX | MMAudio | LatentEQ (Spectrogram) | |
|---|---|---|---|---|---|---|
| Mel |  |  |  |  |  |  |
| Video |
03.
| Ground Truth | V-AURA | Frieren | AudioX | MMAudio | LatentEQ (Spectrogram) | |
|---|---|---|---|---|---|---|
| Mel |  | 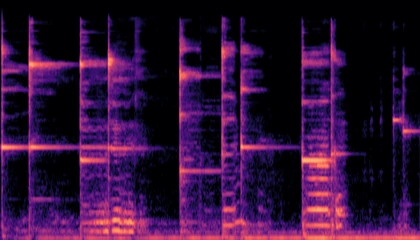 | 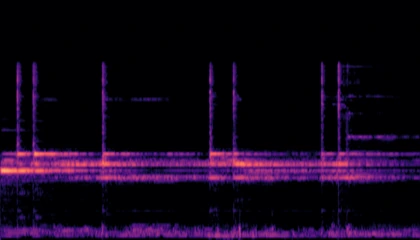 | 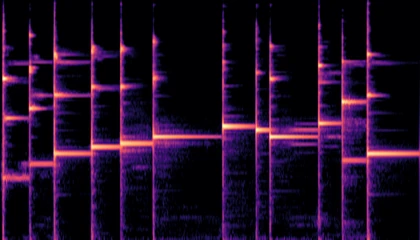 | 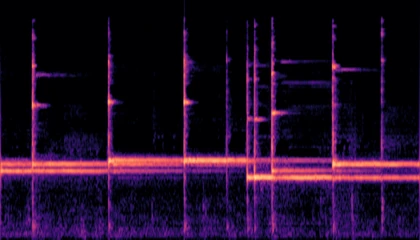 |  |
| Video |
04.
| Ground Truth | V-AURA | Frieren | AudioX | MMAudio | LatentEQ (Spectrogram) | |
|---|---|---|---|---|---|---|
| Mel |  |  |  |  |  |  |
| Video |
05.
| Ground Truth | V-AURA | Frieren | AudioX | MMAudio | LatentEQ (Spectrogram) | |
|---|---|---|---|---|---|---|
| Mel |  |  |  |  |  |  |
| Video |
06.
| Ground Truth | V-AURA | Frieren | AudioX | MMAudio | LatentEQ (Spectrogram) | |
|---|---|---|---|---|---|---|
| Mel |  |  |  |  |  |  |
| Video |
Video-and-Text-to-Audio
VGGSound-Omni
01.
Electronic dance music with a funky bassline and steady beat plays as a DJ rhythmically scratches and stutters a male vocal sample, creating a percussive effect.
| Ground Truth | HunyuanVideo Foley | AudioX | MMAudio | ThinkSound | LatentEQ (Spectrogram) | |
|---|---|---|---|---|---|---|
| Mel |  |  |  |  |  |  |
| Video |
02.
A man's declarative voice speaks in a South Asian language, accompanied by the persistent background gobbling and cooing of a flock of turkeys.
| Ground Truth | HunyuanVideo Foley | AudioX | MMAudio | ThinkSound | LatentEQ (Spectrogram) | |
|---|---|---|---|---|---|---|
| Mel |  |  |  |  |  |  |
| Video |
03.
A male speaks excitedly in Japanese over dramatic orchestral battle music and video game combat sounds, including whooshes and a creature's roar.
| Ground Truth | HunyuanVideo Foley | AudioX | MMAudio | ThinkSound | LatentEQ (Spectrogram) | |
|---|---|---|---|---|---|---|
| Mel |  | 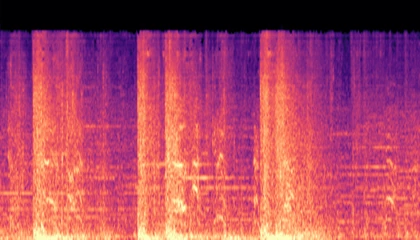 | 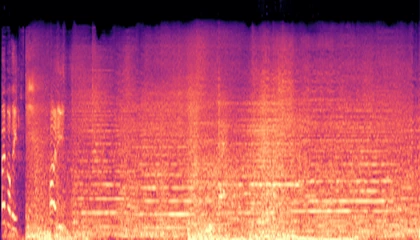 | 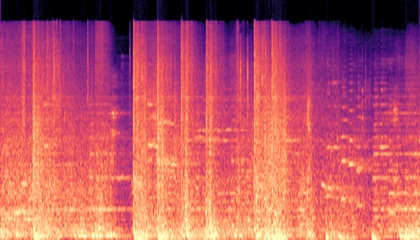 | 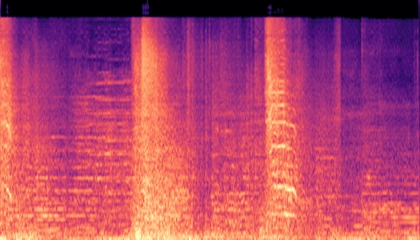 | 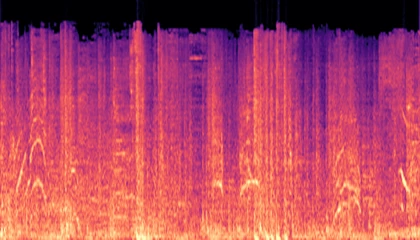 |
| Video |
04.
A single electronic tone and mechanical clicks precede a whirring sound. A rapid series of loud explosions follows, ending with a deafening metallic crash and a final click.
| Ground Truth | HunyuanVideo Foley | AudioX | MMAudio | ThinkSound | LatentEQ (Spectrogram) | |
|---|---|---|---|---|---|---|
| Mel | 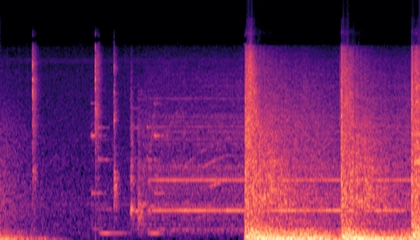 | 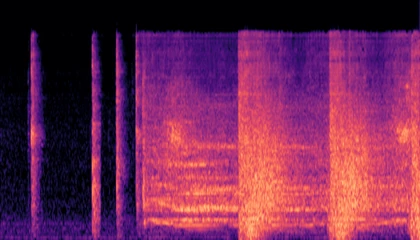 | 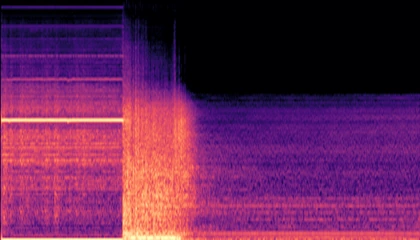 | 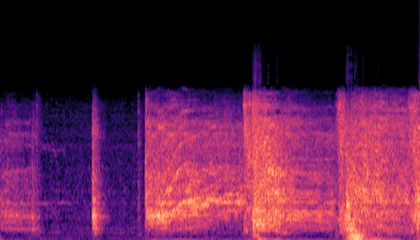 | 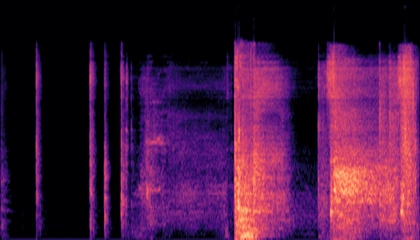 | 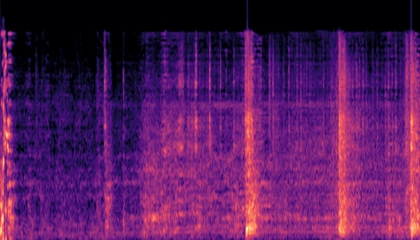 |
| Video |
05.
Upbeat dance music plays as children joyfully chant in unison, accompanied by rhythmic clapping and the steady thud of a jump rope hitting the floor.
| Ground Truth | HunyuanVideo Foley | AudioX | MMAudio | ThinkSound | LatentEQ (Spectrogram) | |
|---|---|---|---|---|---|---|
| Mel | 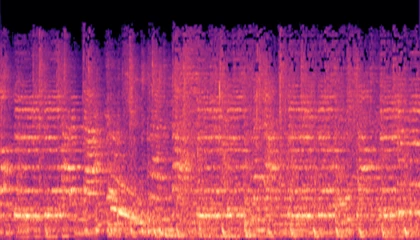 |  |  |  |  | 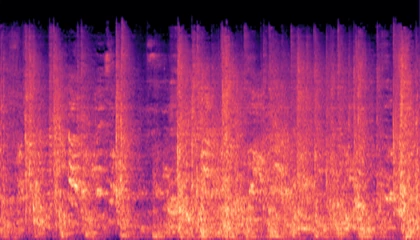 |
| Video |
06.
A fire truck's piercing siren wails continuously, accompanied by a blaring horn. A male voice speaks briefly over the roaring engine as the truck speeds by.
| Ground Truth | HunyuanVideo Foley | AudioX | MMAudio | ThinkSound | LatentEQ (Spectrogram) | |
|---|---|---|---|---|---|---|
| Mel | 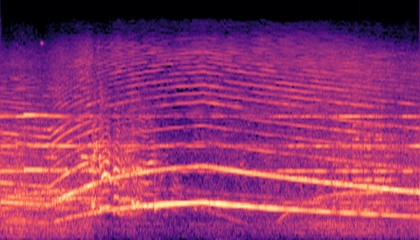 | 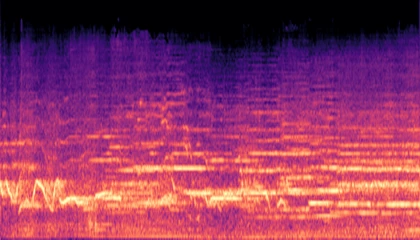 | 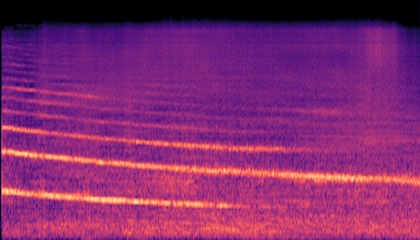 | 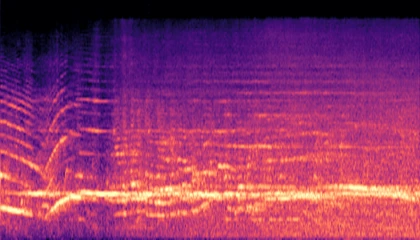 | 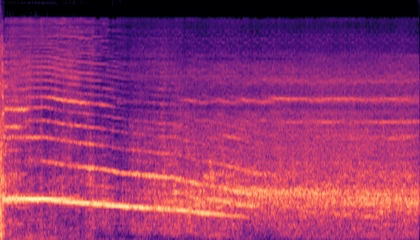 | 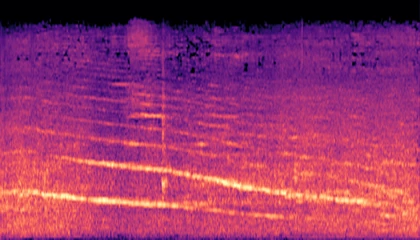 |
| Video |
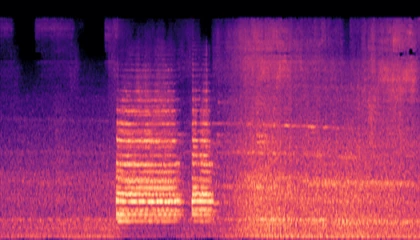
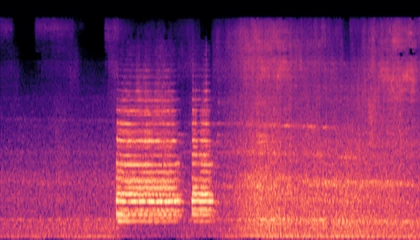
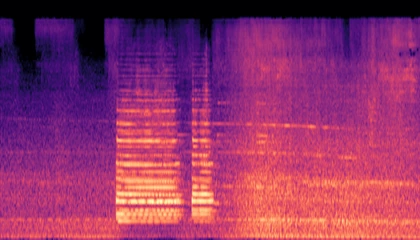
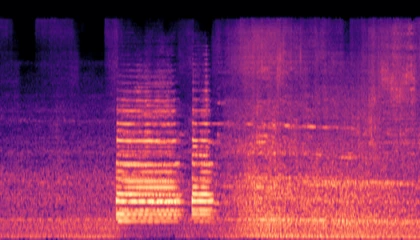
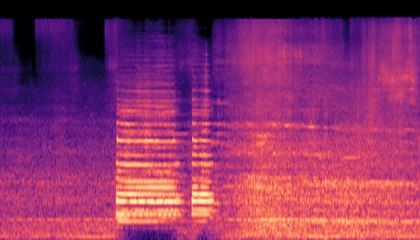
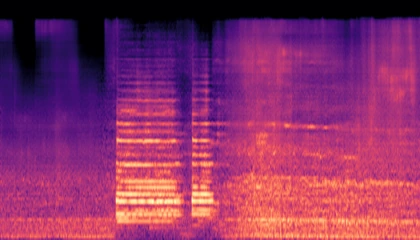
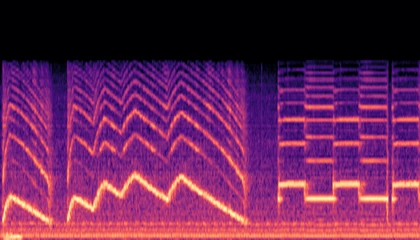
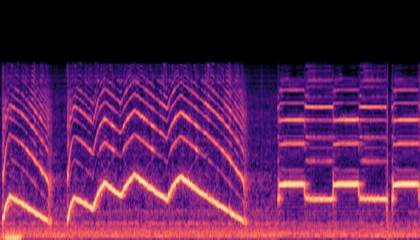
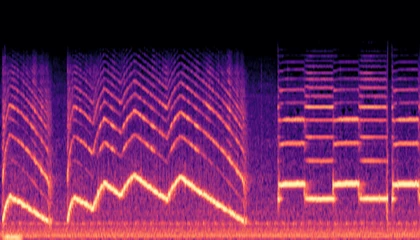
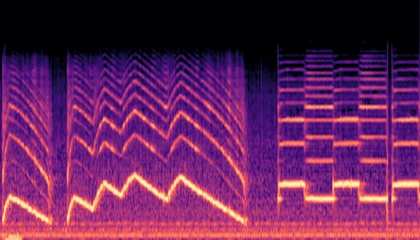
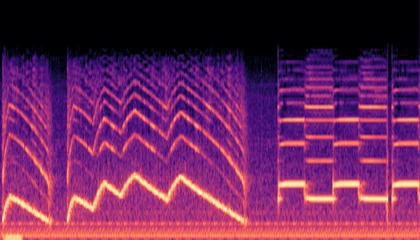
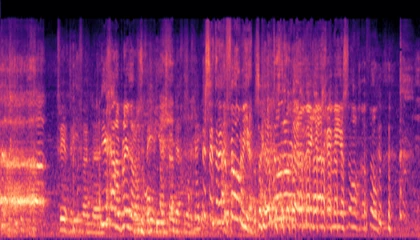
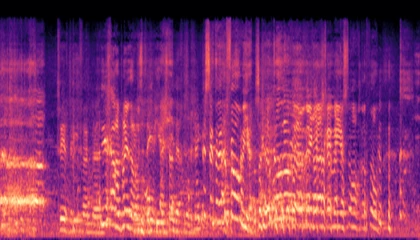
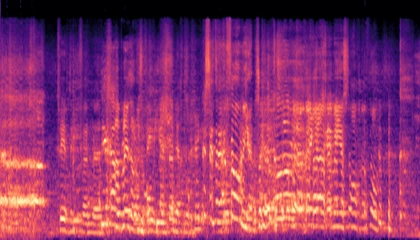
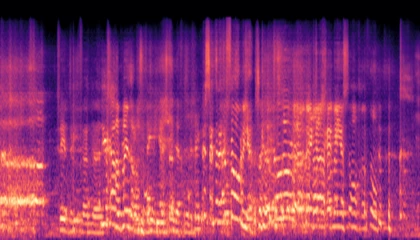
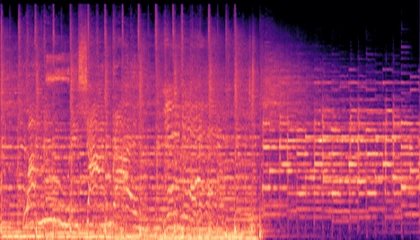
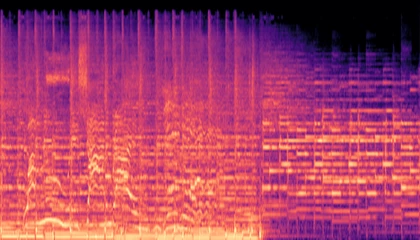
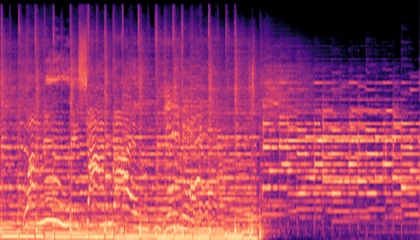
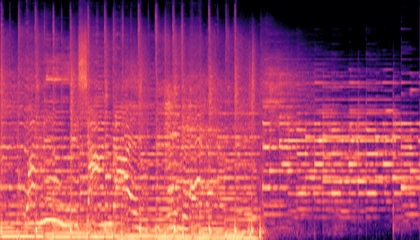
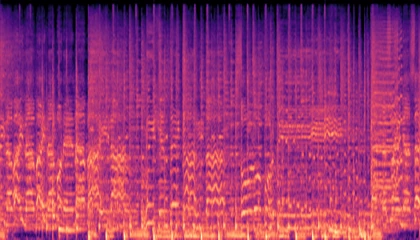
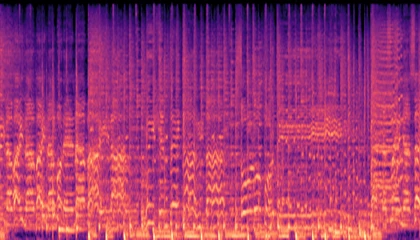
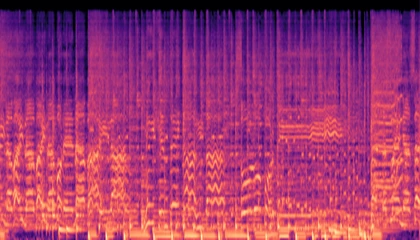
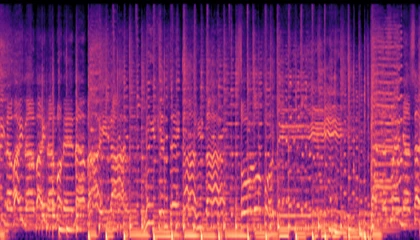
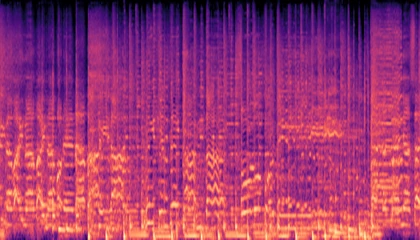
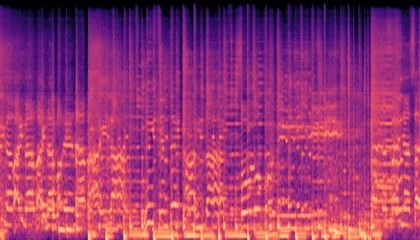
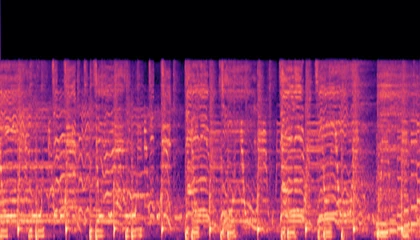
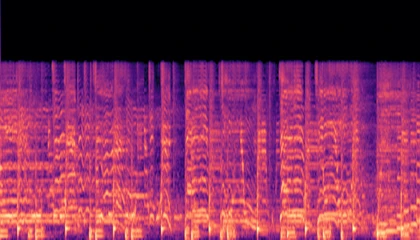
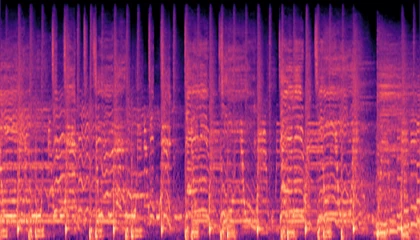
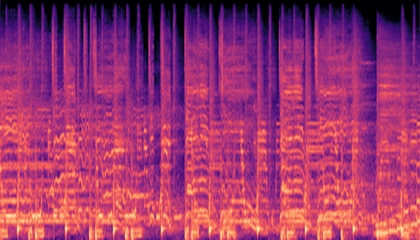
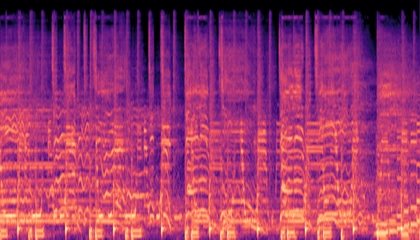
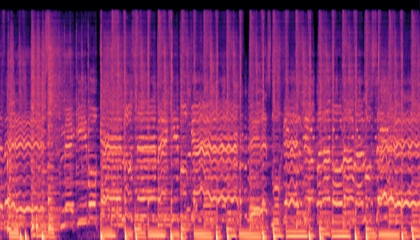
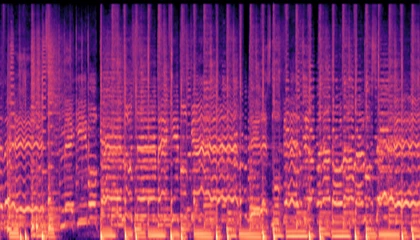
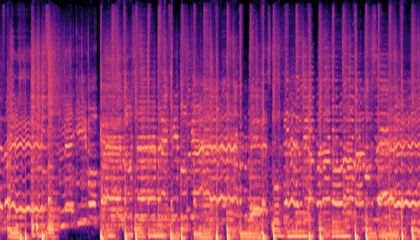
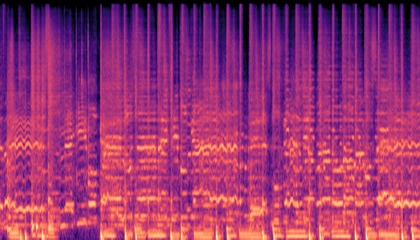
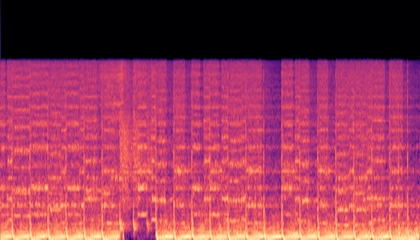
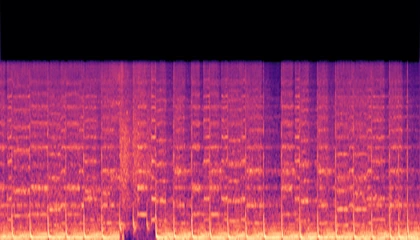
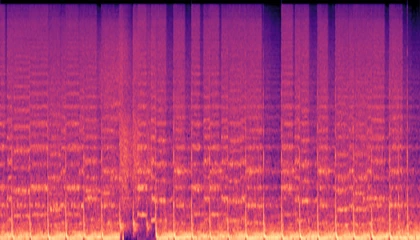
VAE Reconstruction
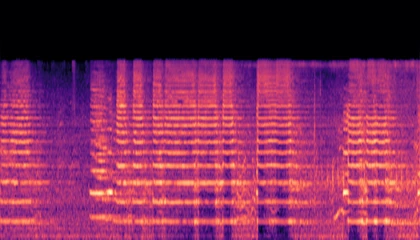
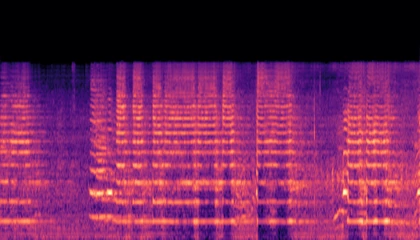
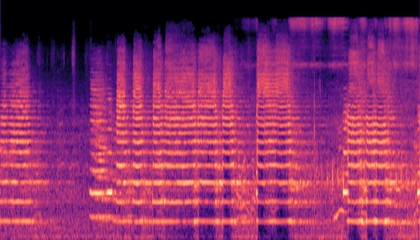
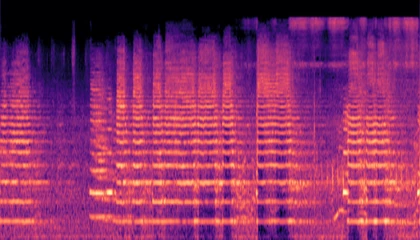
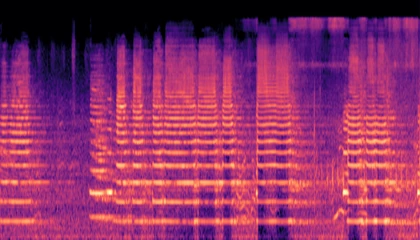
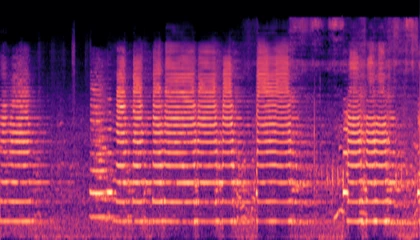
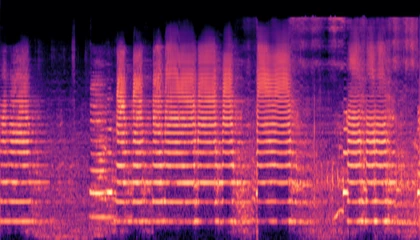
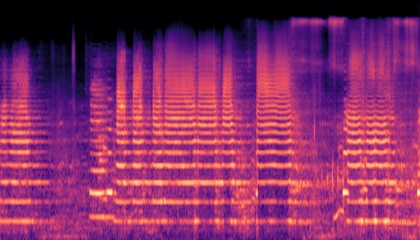
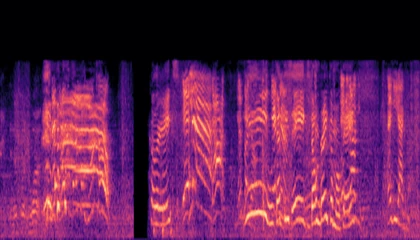
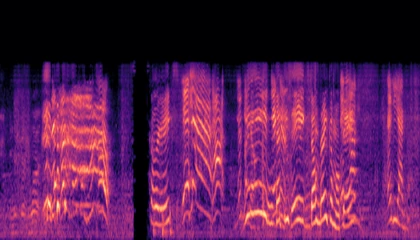
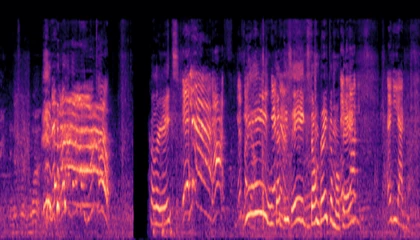
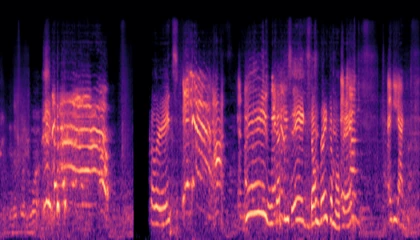
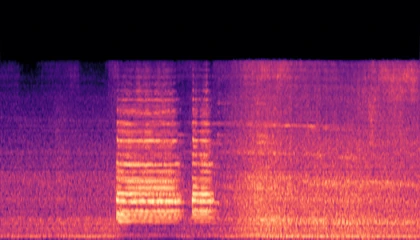
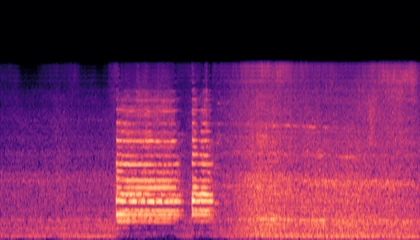
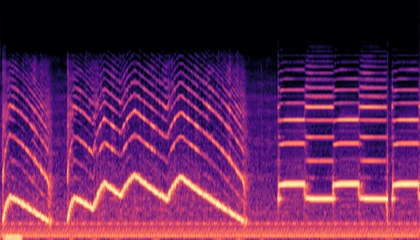
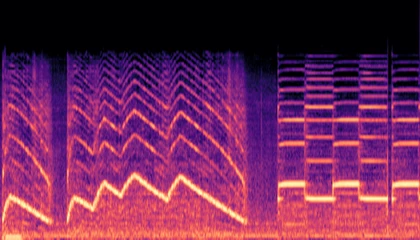
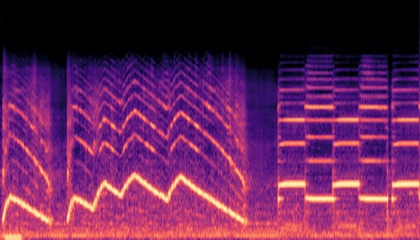
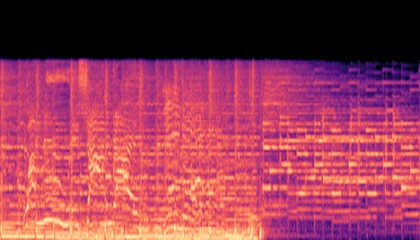
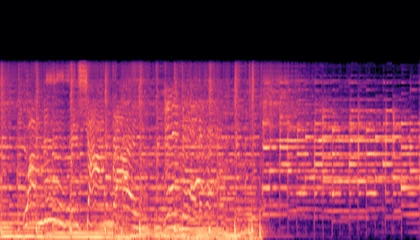
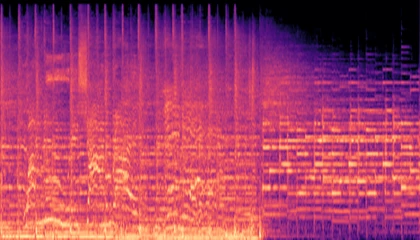
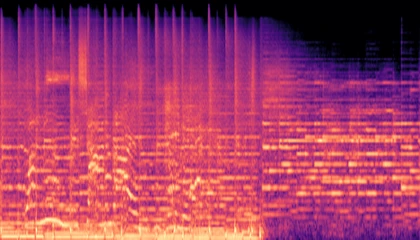
Mel-spectrograms and audio of the same 10-second input reconstructed by each VAE.
Sound
01.
| Ground Truth | AudioLDM | Make-An-Audio 2 | MMAudio | LatentEQ (Spectrogram) | HunyuanVideo Foley | εar-VAE | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel | 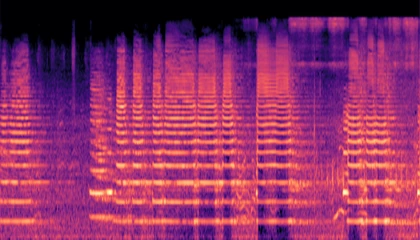 |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
02.
| Ground Truth | AudioLDM | Make-An-Audio 2 | MMAudio | LatentEQ (Spectrogram) | HunyuanVideo Foley | εar-VAE | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel | 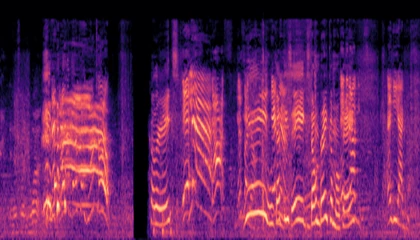 |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
03.
| Ground Truth | AudioLDM | Make-An-Audio 2 | MMAudio | LatentEQ (Spectrogram) | HunyuanVideo Foley | εar-VAE | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel | 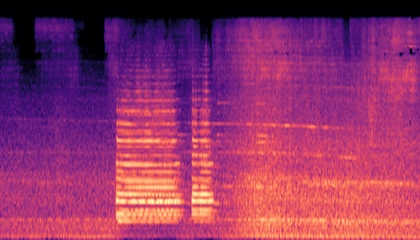 |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
04.
| Ground Truth | AudioLDM | Make-An-Audio 2 | MMAudio | LatentEQ (Spectrogram) | HunyuanVideo Foley | εar-VAE | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel | 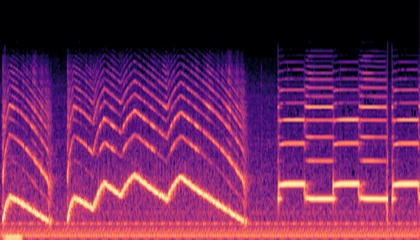 |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
05.
| Ground Truth | AudioLDM | Make-An-Audio 2 | MMAudio | LatentEQ (Spectrogram) | HunyuanVideo Foley | εar-VAE | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel |  |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
Music
01.
| Ground Truth | AudioLDM | Make-An-Audio 2 | MMAudio | LatentEQ (Spectrogram) | HunyuanVideo Foley | εar-VAE | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel | 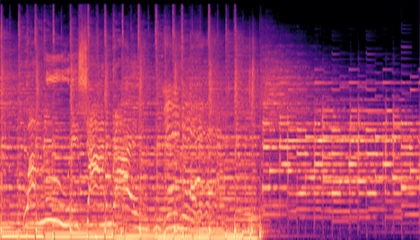 |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
02.
| Ground Truth | AudioLDM | Make-An-Audio 2 | MMAudio | LatentEQ (Spectrogram) | HunyuanVideo Foley | εar-VAE | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel | 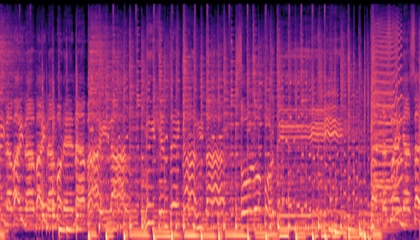 |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
03.
| Ground Truth | AudioLDM | Make-An-Audio 2 | MMAudio | LatentEQ (Spectrogram) | HunyuanVideo Foley | εar-VAE | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel | 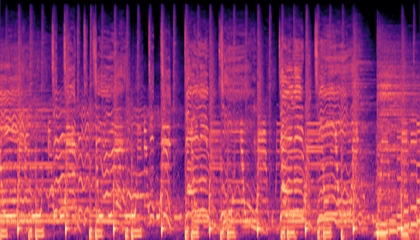 |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
04.
| Ground Truth | AudioLDM | Make-An-Audio 2 | MMAudio | LatentEQ (Spectrogram) | HunyuanVideo Foley | εar-VAE | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel |  |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
05.
| Ground Truth | AudioLDM | Make-An-Audio 2 | MMAudio | LatentEQ (Spectrogram) | HunyuanVideo Foley | εar-VAE | Stable Audio Open | LatentEQ (Waveform) | |
|---|---|---|---|---|---|---|---|---|---|
| Mel | 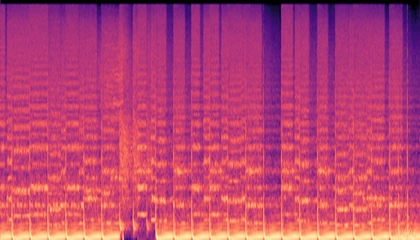 |
 |
 |
 |
 |
 |
 |
 |
 |
| Audio |
Figure 2, Enlarged